Burrow
A self-hosted data ingestion pipeline and retrieval API that streamlines and accelerates the development of RAG applications
A self-hosted data ingestion pipeline and retrieval API that streamlines and accelerates the development of RAG applications
Ease of getting documents into a database via both friendly GUI and RESTful endpoints, the pipeline takes care of the rest.
Layout-aware document processing and structure-preserving chunking, combined with an API offering hybrid search, reranking, and metadata filtering.
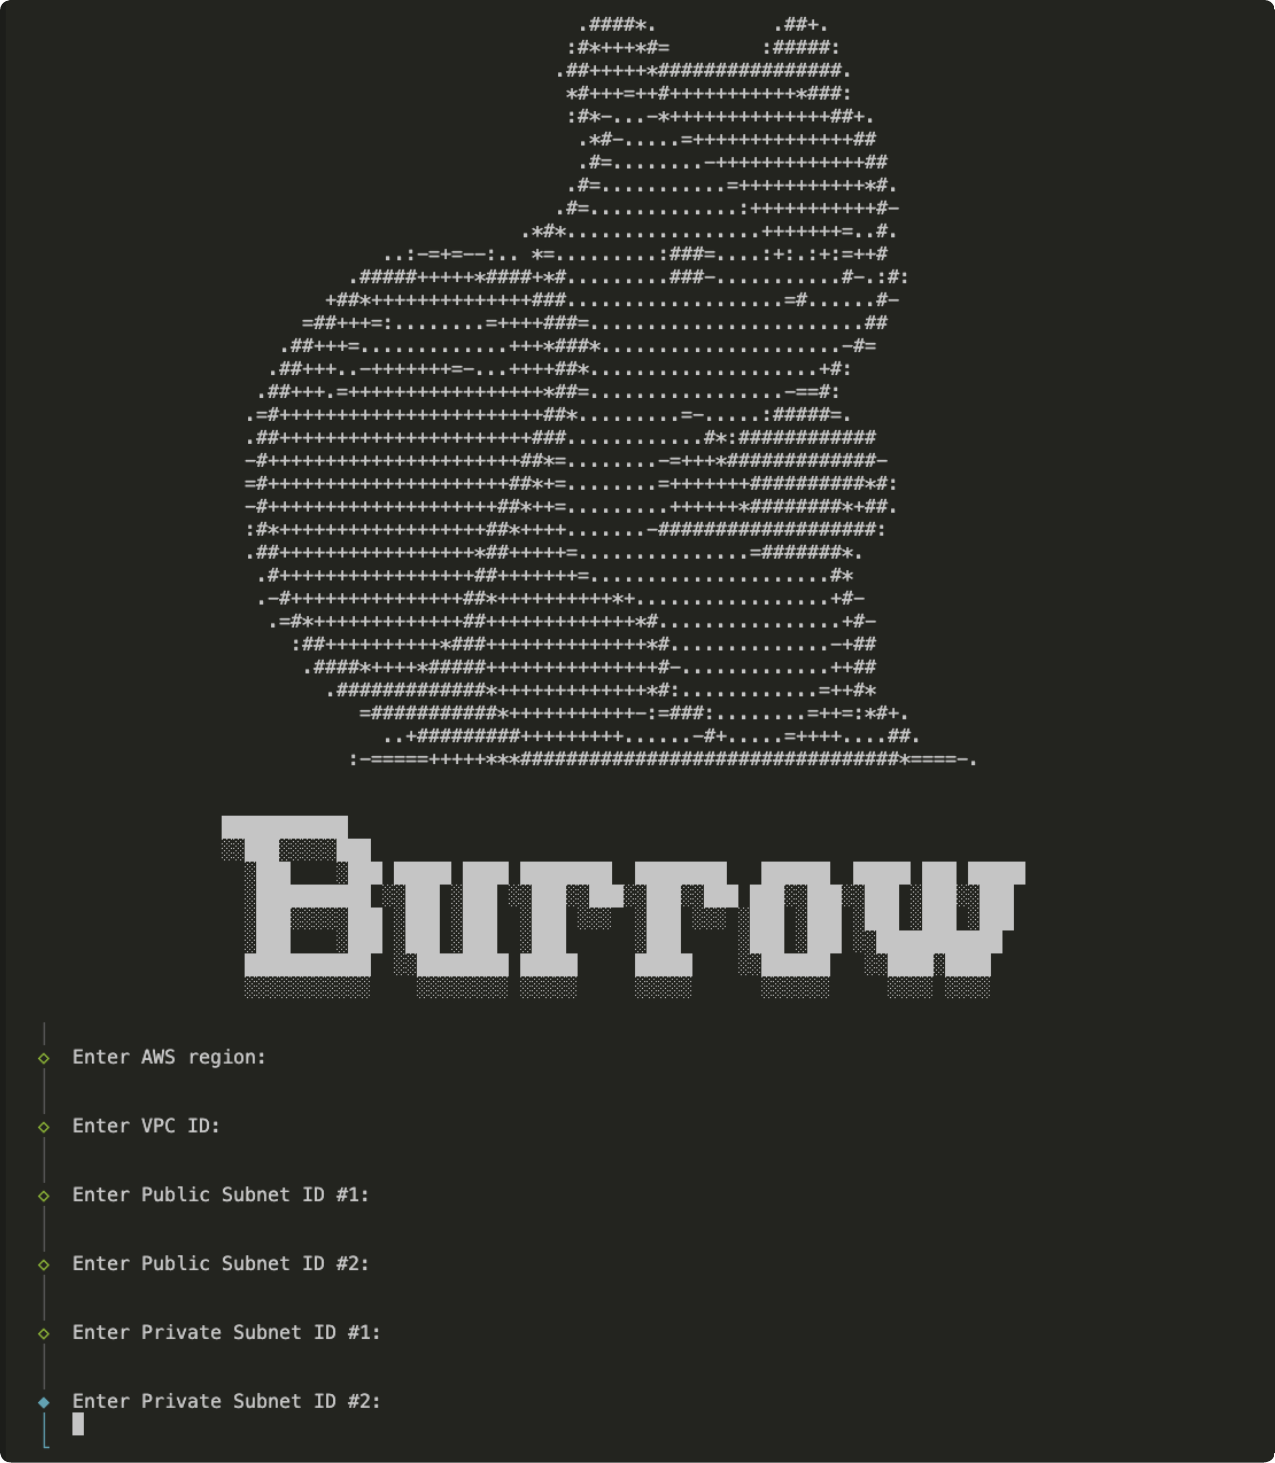
Automated deployment to your AWS environment using a self-hosted, serverless architecture where performance and cost scale based on usage patterns.